Unlimited OCR 是一款专为长文本与多页文档打造的 OCR 解析引擎,将单次推理的视野
Unlimited OCR 是一款专为长文本与多页文档打造的 OCR 解析引擎,将单次推理的视野从单页扩展到整篇文档,真正实现「一镜到底」的高精度解析。
TechFoco


共 17 篇文章,按时间倒序展示。
Unlimited OCR 是一款专为长文本与多页文档打造的 OCR 解析引擎,将单次推理的视野从单页扩展到整篇文档,真正实现「一镜到底」的高精度解析。
OCR识别需要多个工具,布局分析工具拆分文档结构,文本识别模型提取内容,还要额外的手动后处理,来回切换效率低下。

DeepOCR -- DeepSeek-OCR的完全开源复现项目 DeepSeek-OCR的开源是只包含权重和技术报告,想复现还是有些难度。
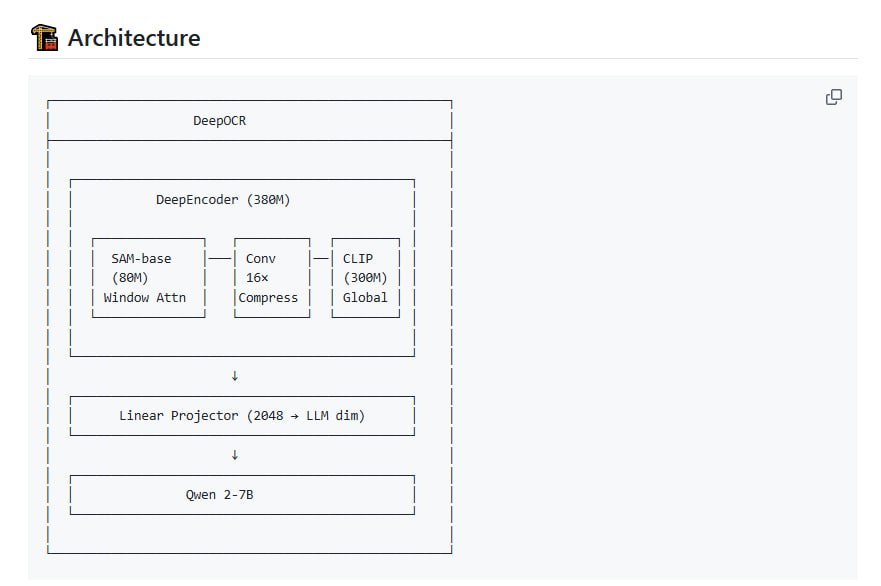
DeepOCR -- DeepSeek-OCR的完全开源复现项目 DeepSeek-OCR的开源是只包含权重和技术报告,想复现还是有些难度。
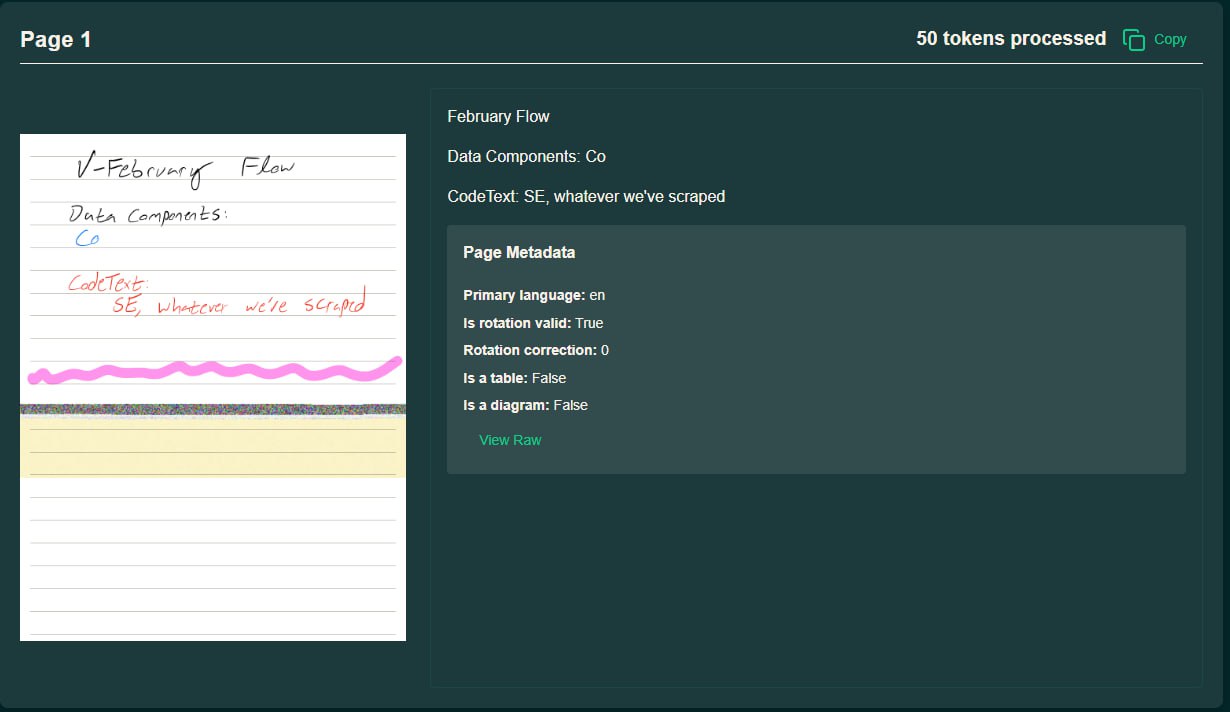
Chandra OCR开源发布,具备强大功能和广泛应用潜力: - 支持完整版面信息解析,能识别并标注图片、图表 - 优秀的手写体、表格和表单识别能力 - 兼容transformers和vLLM架构,易于集成和扩展 获取方式: Huggingface仓库 | Github代码库 | 在线演示体验(推荐平衡模式) 通过Datalab API调用,支持balanced和accurate两种模式 快速上手: pip install chandra-ocr chandra_vllm chandra input.pdf ./output 性能与对比: - 在olmocr基准测试中优于Deepseek OCR,展现出更高准确率 - 相较Marker OCR,Chandra更擅长复杂格式和整体排版,但速度稍慢 - 支持多语言(基于Surya语言支持),但对部分低资源语言仍有提升空间 已知限制: - 纯数学公式识别尚不及Marker - 旋转页面识别准确度下降 - 部分低资源语言效果欠佳 未来计划: - 持续优化模型精度和性能 - 量化与加速支持,提升推理速度 - 扩展语言和用例覆盖
开源OCR模型运行成本低且注重隐私保护,但市面上新模型层出不穷,如DeepSeek-OCR、Nanonets、PaddleOCR,选哪个成了难题。
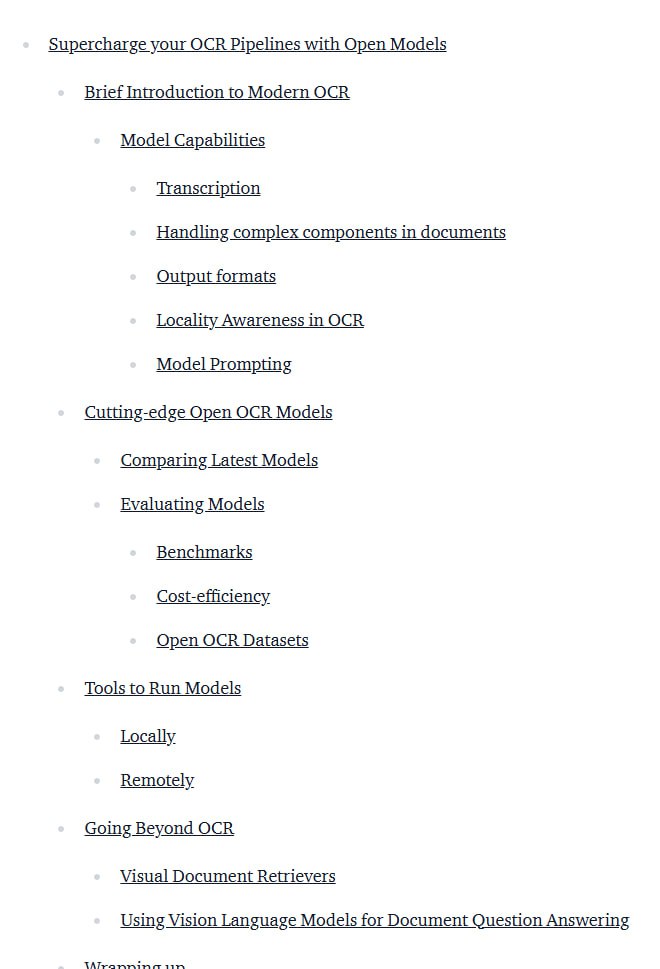
开源OCR模型运行成本低且注重隐私保护,但市面上新模型层出不穷,如DeepSeek-OCR、Nanonets、PaddleOCR,选哪个成了难题。
Nanonets-OCR2:颠覆传统OCR,智能将文档转为结构化Markdown Nanonets推出的OCR2系列,是业内领先的图像转Markdown模型,不仅提取文本,更实现智能内容识别与语义标注,极大提升LLM后续处理效率。
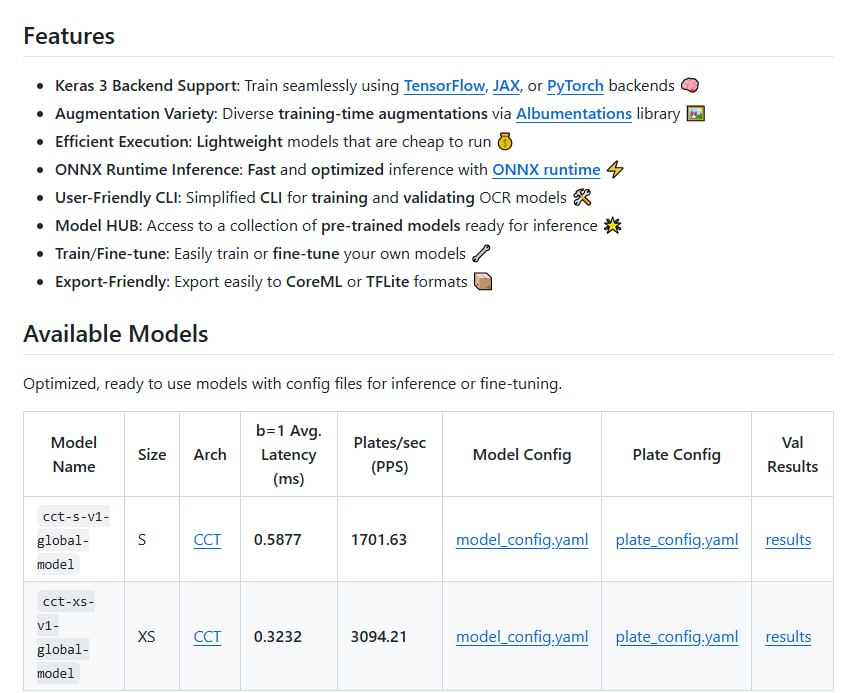
PHOCR:面向多语种场景的高性能开源OCR工具包,专注突破文本识别精度瓶颈,实现行业级识别率提升。
通用 PDF 文件流 OCR 到文本 API 接口 图像/转换 高可用图像识别引擎 基于机器学习 / 高效文本提取 文件处理 / OCR。
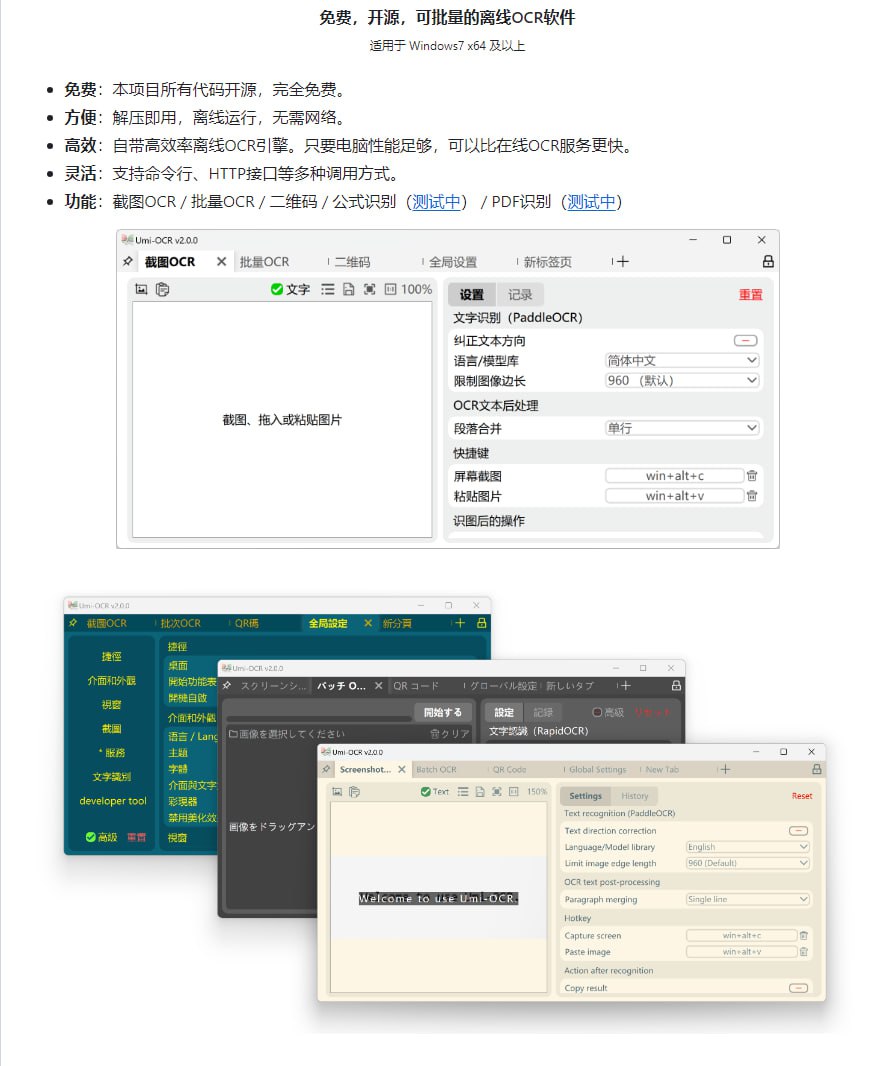
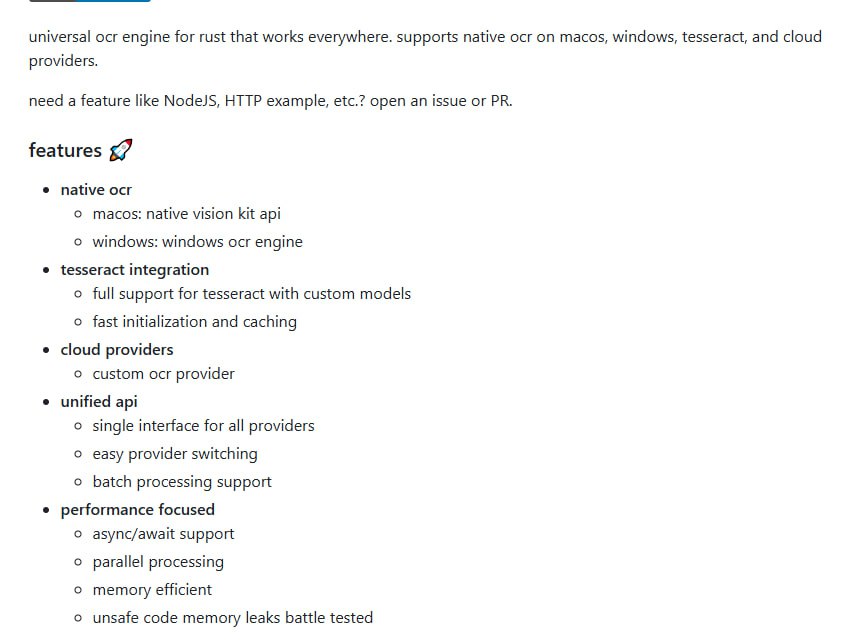
一个跨平台的原生OCR工具,为MacOS、Windows和Linux用户提供强大的文字识别能力。
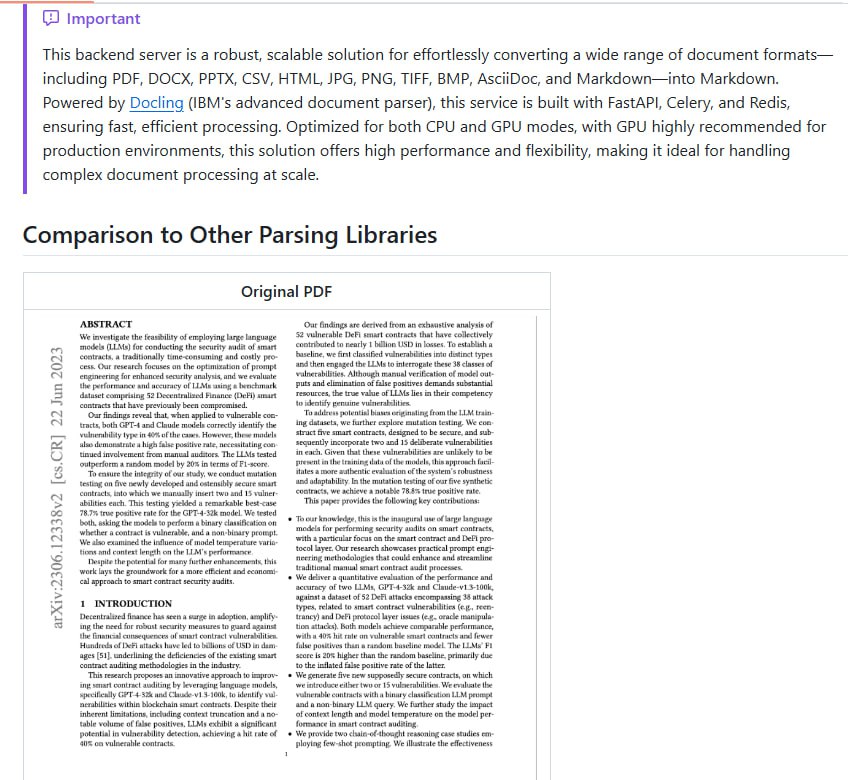
docling-api:高效、可扩展的文档转换后端服务器,轻松将多种文档格式(PDF、DOCX、PPTX、HTML、图片等)转换为Markdown。
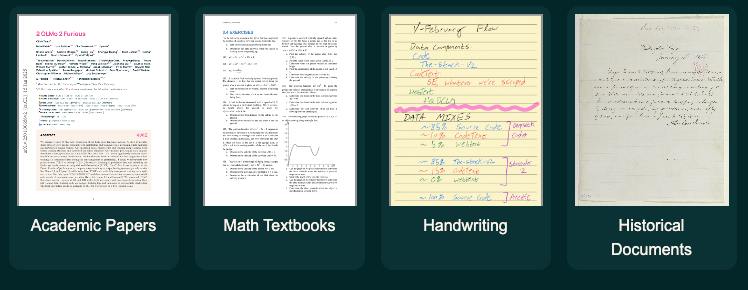
olmOCR is an open-source tool designed for high-throughput conversion of PDFs and other documents into plain text while preserving natural reading order. It supports tables, equations, handwriting, and more. olmOCR has been trained on academic papers, technical documentation, and other reference content, and uses a unique prompting technique to increase accuracy and decrease hallucinations. For full details on the recipe, read our technical report. The current model was fine-tuned on English documents; other languages are not likely to work. Try the demo on your own documents below. You can then deploy the full olmOCR toolkit on your own GPUs for efficient, scalable document processing—at an estimated cost of just $190 USD per million pages converted.
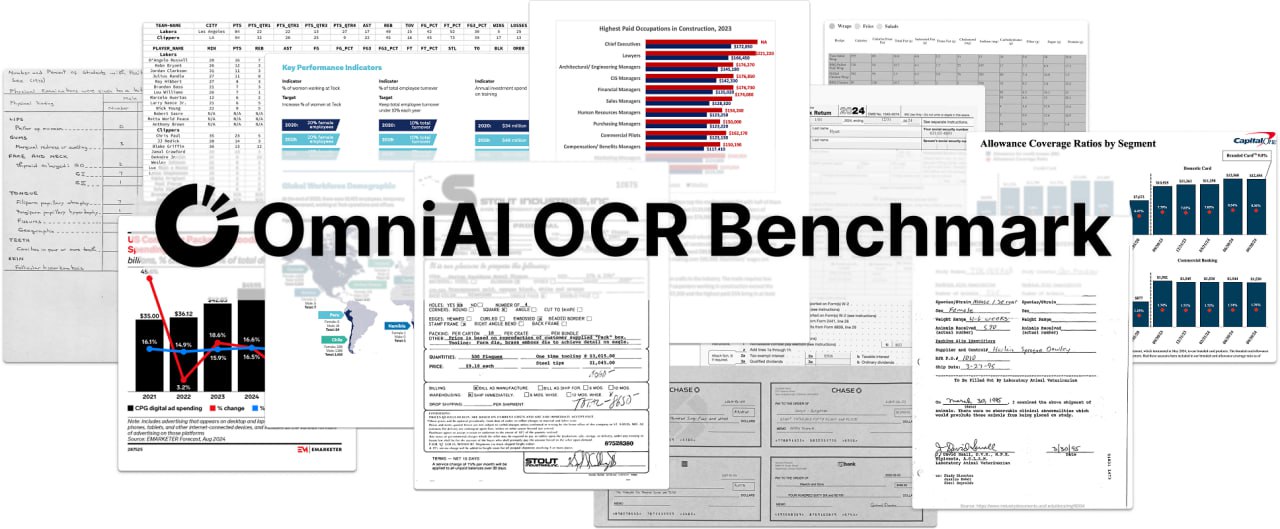
一个强大的OCR基准测试工具,帮助你快速评估不同多模态模型的OCR和数据提取能力,轻松找到最适合你的模型。